
AI Infrastructure for 2027: The Data and Orchestration Layers Agentic AI Needs
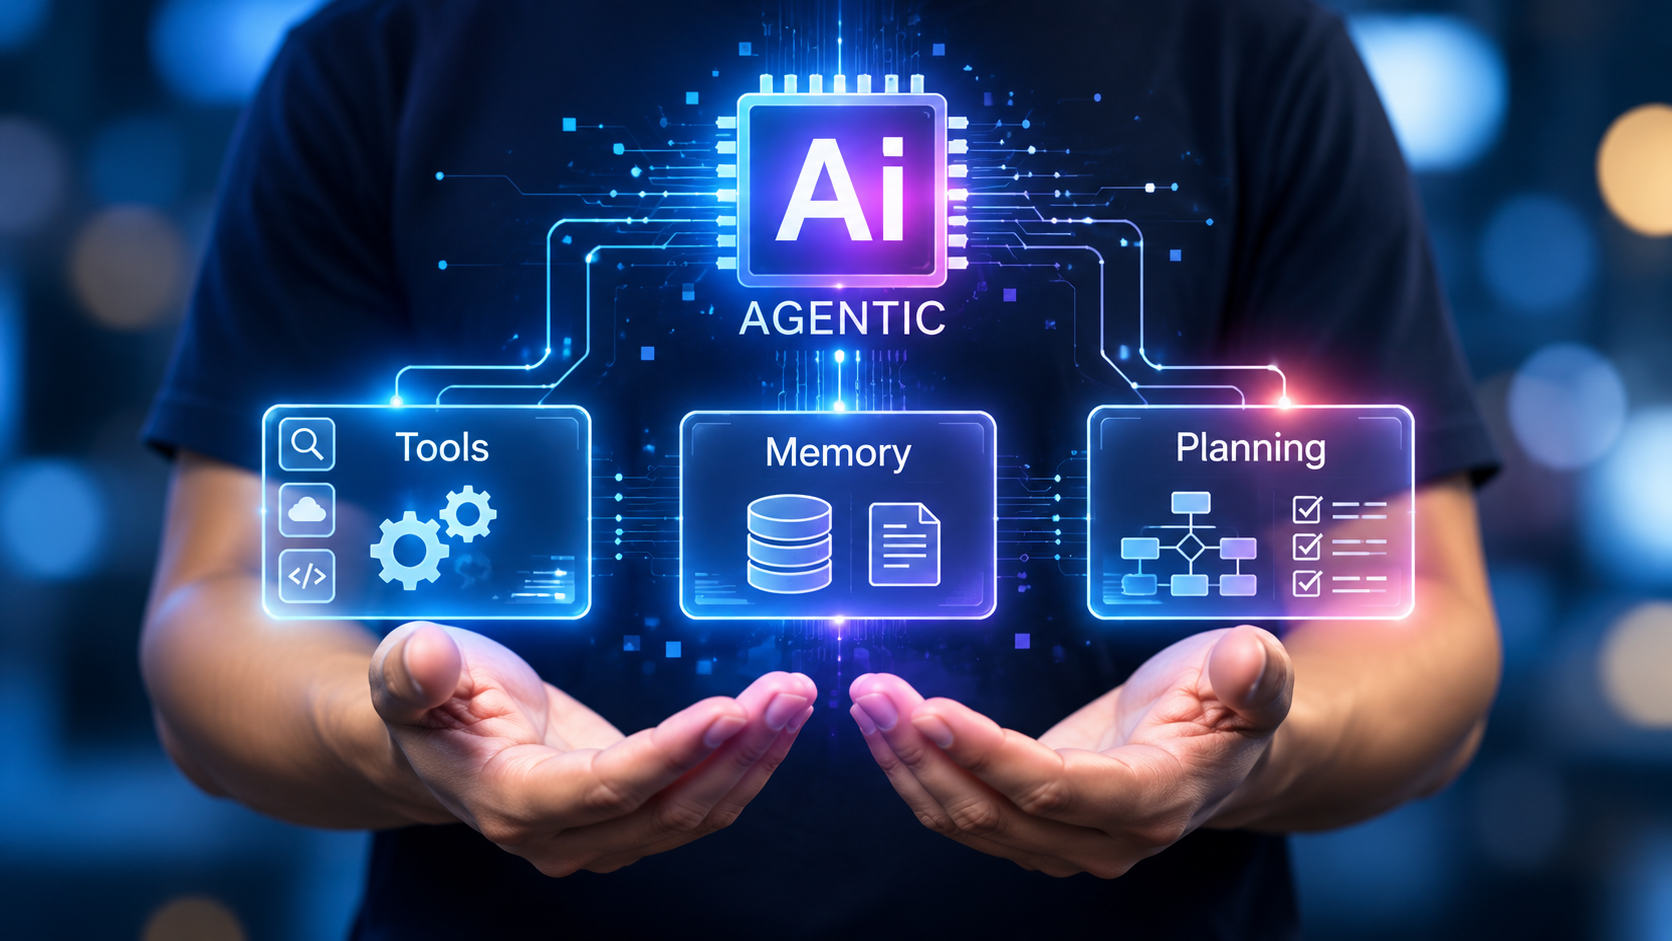
The models are no longer the bottleneck. As Patrick Moorhead put it at Google Cloud Next 2026, "In the age of agentic AI, your data has to be cleaner than it needed to be before." By 2027, the organizations that get value from AI agents will be the ones that solved two unglamorous problems first: getting the right data to the agent at the moment it decides something, and coordinating what dozens of agents do with that data without losing control. Futurum Research's 1H 2026 Data Intelligence, Analytics, and Infrastructure Decision Maker Survey found enterprise agentic AI adoption leveling off at 47%, with more than a quarter of technology leaders citing data integration difficulties as their primary bottleneck. Futurum's 2H 2026 CIO & Technology Buyers survey of 1,636 decision makers found 46.9% of organizations running AI spend over budget, and Futurum's 2026 Key Issues and Predictions puts the share of organizations struggling to establish production governance at 93%. Integration, cost, and governance: each of those failure modes traces back to infrastructure, not to the intelligence of the model.
Six Five Media has spent 2026 putting this problem to the executives building the agentic stack, from RSAC and Google Cloud Next to Dell Technologies World. This piece pulls those conversations together with research from Futurum and Moor Insights & Strategy to lay out what the data and orchestration layers for agentic AI need to look like heading into 2027, what is blocking teams today, and the order in which to do the work.
What "agentic AI data" actually means
Agentic AI data is the data an autonomous agent needs to plan, act, and verify its own work: not just training data, but live operational context (records, documents, events, tool outputs), the metadata that tells the agent whether that context is fresh and trustworthy, the memory of what the agent has already done, and the audit trail of what it decided and why. A chatbot can survive on a static knowledge base. An agent that creates a purchase order or reroutes a shipment cannot.
That distinction changes the infrastructure requirement. Traditional analytics pipelines were built to move data in batches to the humans who interpret it. Agents consume data continuously, in the middle of a task, and act on it without a human reading the intermediate result. The data layer therefore has to carry provenance, freshness, and permission information alongside the data itself, and the orchestration layer has to enforce what an agent may do with it. As Snowflake's Pavan Pothukuchi put it in a Six Five conversation with Futurum's Brad Shimmin, agent autonomy has become a data architecture decision.
Why data readiness, not model capability, is the 2027 blocker
"Data governance is everything," Patrick Moorhead said as he opened a conversation with Veeam at RSAC 2026. The survey evidence backs him up, and it is unusually consistent:
- In Futurum's 1H 2026 data and infrastructure survey of 818 decision makers, integration friction (29%) and the lack of safe transactional write-back (25%) together account for more than half of the hurdles organizations name when agents need to read and write data.
- Futurum's research on 444 organizations building their own AI applications found 67.3% still name data quality as a challenge for incorporating data into AI, while data labeling and enrichment is the only challenge still rising, up to 40.5%.
- In Futurum's 1H 2026 AI Platforms survey, 55.4% of enterprise technology leaders name agent reliability and hallucination management as their top hurdle to scaling generative AI, and 51.2% of organizations building internal AI applications report ongoing data quality and availability challenges.
- Futurum's 1H 2026 Cybersecurity Decision-Makers Survey (N=929) found 55% of respondents lack the technical ability to detect or contain a compromised AI agent operating at machine speed, and 54% are concerned that existing software vendors are adding autonomous agents without sufficient visibility or security controls.
Read together, these numbers describe a single situation. Moor Insights & Strategy notes that for many enterprise AI programs, the data itself is now a tighter constraint than the models or the infrastructure, and most of that data is unstructured, with very little parsed, enriched, and indexed so a model can retrieve it. Most of it is not connected to the systems where agents run, teams are still working through its quality, and security teams cannot reliably see what agents do with it. An agent dropped into that environment will confidently act on stale documents and partial records. Futurum's Keith Kirkpatrick makes the related point that agentic AI fails when it is "thrown on top of" an unchanged operating model and succeeds when the underlying process is redesigned. The same analysis finds that organizations behind their competitors are far more likely to cite legacy-system integration as a barrier, a 13.1-point gap.
Adoption pressure is rising regardless. Futurum's 1H 2026 Enterprise Software Decision Maker Survey found autonomous agents and agentic AI claimed the number-one technology priority for 17.1% of 830 IT decision makers, up from 13.0% six months earlier, making it the fastest-growing category in the survey. Futurum sizes the AI platforms market at $109.9 billion in CY2025, on a base-case path to $496.9 billion by CY2030. Yet only 13.3% of organizations have reached Futurum's most advanced AI maturity stage. The agents are arriving whether or not the data is ready for them.
The agentic AI data stack for 2027
Six Five analysts separate the data side of the architecture into five layers. An organization that already owns a warehouse, a catalog, and a search index has a starting point in several of them; the 2027 work is making each layer agent-aware.
1. Storage and ingestion: the lakehouse as the system of record for agents
Agents need one governed place to read structured and unstructured data with the same access controls. The practical pattern is a lakehouse (open table formats over object storage) that ingests documents, tickets, emails, and event streams alongside transactional tables, so that a retrieval call and a SQL call hit the same permissions model. Futurum's data survey found 77% of organizations are implementing, piloting, or strongly considering a lakehouse built on open table formats. The problem to attack here is the one Moor Insights & Strategy describes: most organizations operate across fragmented data estates (ERP, CRM, data warehouses, SaaS platforms and object stores) with no unified access layer, and agents operating downstream of that fragmentation produce incomplete or unreliable outputs. Every disconnected system is a blind spot the agent will not know it has.
2. Context and metadata: the layer that makes data safe to act on
This is the layer the market is now investing in. 44.5% of enterprise technology leaders plan to invest more in dedicated semantic layers over the next 24 months, according to Futurum, and Futurum's market forecast has the Semantic & Context Layer posting the highest growth rate of any data sub-market in every year through CY2031. It holds the metadata an agent needs to judge its inputs: lineage (where did this come from), freshness (when was it last updated), ownership, sensitivity classification, and the business definitions in a semantic layer that map "active customer" or "net revenue" to one agreed computation. Without it, two agents can answer the same question differently, and neither can explain why, which is the problem Moor Insights & Strategy describes as two teams asking the same question and getting two different answers. Freshness is the failure mode that bites first: as Dell ISG CTO Ihab Tarazi told Patrick Moorhead and Daniel Newman at Dell Technologies World 2026, agents not only need to get to all the data, "they need to know what's the most recent file is."
3. Retrieval and memory: vectors, graphs and state
Retrieval for agents goes beyond a single vector index. Production patterns combine vector search for semantic similarity, knowledge graphs for relationships between entities, and structured queries for exact facts, with the semantic layer deciding which to use. Most enterprises are not there yet: Futurum found 59.4% of enterprise RAG architectures remain limited to basic or hybrid search. Memory needs the same design attention as retrieval: short-term working memory for the current task, episodic memory of past runs, and long-term memory of learned preferences, each with its own retention and access rules. Moor Insights & Strategy warns that assembling LLM APIs, vector stores, RAG pipelines, memory layers and workflow orchestration separately creates a fragile architecture in which each additional component introduces failure points and governance gaps. An agent that cannot remember it already emailed a customer will email them twice.
4. Real-time streams: data that arrives while the agent is acting
Batch-refreshed data is a liability for agents that act in minutes. Inventory, pricing, fraud signals, and system health change faster than nightly pipelines refresh. As a Six Five panel with Dell and Samsung observed, "continuous agents demand real-time access to memory, storage, and dynamic data environments — not systems designed for batch workloads." Event streaming lets agents subscribe to changes rather than poll for them, and lets the orchestration layer interrupt an agent when its assumptions become invalid mid-task.
5. Governance and observability: logs that can stand up to an auditor
Every layer above produces evidence that needs to be retained: which data the agent read, which tool it called, which model version produced the plan, and which human (if any) approved the action. Futurum's Brad Shimmin frames the bar in the 2026 Key Issues and Predictions report: "It's about letting an agent change a record and being able to prove exactly who authorized it, why it happened, and how to reverse it." This is also where regulation lands, covered below.
Orchestration: the protocols that are becoming the plumbing
Two open protocols now aim to standardize how agents reach tools and each other. That matters for data teams because a shared protocol lets the data layer enforce one set of rules regardless of which vendor built the agent.
Model Context Protocol (MCP): agents to data and tools
The Model Context Protocol is an open standard, originally from Anthropic, that defines how LLM applications connect to external data sources and tools over JSON-RPC 2.0. Servers expose three things: resources (context and data), prompts (templated workflows), and tools (functions the model can execute). The current specification adds optional extensions for asynchronous long-running tasks and for structured skills. For data teams, the useful consequence is that a data product can be published once as an MCP server, with its access controls, and consumed by any compliant agent host.
Adoption is already widespread. On Ep. 302 of The Six Five Pod, the hosts flagged Google's commitment to place MCP servers across its data surfaces, so even customers not locked into Google's platform can tap that data. Futurum's Mitch Ashley reported 97 million monthly MCP downloads around the 2026 MCP Dev Summit, and Futurum's survey data shows 76.2% of organizations with active agentic AI interest running MCP in production, piloting it, or strongly considering it.
The specification is explicit that security is the implementer's job: hosts must obtain explicit user consent before exposing data to servers or invoking any tool, and tool descriptions should be treated as untrusted unless they come from a trusted server. MCP's maintainers have also drawn a clear scope line: the protocol connects AI applications to data sources, while identity, observability, and governance belong to other layers, with agent gateways providing the policy enforcement the protocol itself does not. Kestra's Kai Waehner made the same point on a Six Five virtual webcast: with MCP interfaces now common, connecting an agent to enterprise APIs is the easy part, and access control, data security, and compliance are where deployments get difficult. Those requirements translate directly into orchestration design: consent flows, scoped credentials, a gateway, and a registry of approved servers.
Agent2Agent (A2A): agents to agents
The Agent2Agent protocol, created by Google and moved to the Linux Foundation in June 2025 with support from more than 100 technology companies, including founding participants Cisco, SAP and ServiceNow, covers the other direction: how agents discover one another, exchange information securely and collaborate across vendor and framework boundaries. A2A v1.0 landed alongside the 2026 MCP Dev Summit, formalizing agent-to-agent coordination as a complement to MCP. Futurum cautions that A2A's Signed Agent Cards are an integrity mechanism, not an authorization mechanism: they confirm a capability declaration came from a legitimate source, not that a sub-agent is authorized to use those capabilities. MCP connects an agent to context and tools; A2A connects agents to each other. An orchestration layer for 2027 speaks both, and adds the authorization neither provides.
What agentic orchestration costs
Orchestration decisions have a cost dimension that is easy to miss during pilots. Multi-step agents multiply inference calls per task. Futurum's AI platforms forecast found managed inference reached $23.1 billion in CY2025 versus $16.3 billion for training, overtaking training that year, and projects inference at 71.7% of AI platforms infrastructure spend by CY2030. At the infrastructure level, Futurum notes the five largest US cloud and AI infrastructure providers have committed between $660 billion and $690 billion in 2026 capital expenditure, with agentic deployments driving continuous, multi-step inference.
Those costs are already landing on enterprise budgets. Among the organizations running AI spend over plan in Futurum's CIO survey, only 17.2% pause or reduce the initiative; most ask for more budget or absorb the overrun. Futurum also finds that stuffing context windows with raw schemas and documentation taxes every inference call, and ambiguous context sends agents into retry loops that multiply compute consumption. Moor Insights & Strategy singles out per-employee and per-agent budgets with automatic fallback to cheaper models as some of the most useful governance controls now shipping, while Snowflake's Pothukuchi told Six Five that routing too aggressively can erase cache-hit discounts. Orchestration that caches context, routes simple steps to smaller models and avoids redundant retrieval is now a cost control, not an optimization.
Governance: agents will be audited, so build the trail now
"We used to talk forever about access control, but it's really about agent control at this point," Patrick Moorhead said at RSAC 2026. Daniel Newman has been even more blunt about the risk on The Six Five Pod: "every agent is a badgeless, faceless, nameless reckoning in terms of cyber risk."
Agents act under an identity, and the first governance decision is whose. A service account shared by every agent produces a log that says "the automation did it", which satisfies no auditor. In their Six Five analyst recap of Google Cloud Next 2026, Moor Insights & Strategy's Jason Andersen and Mike Leone and Futurum's Brad Shimmin boiled it down to two questions that gate every production deployment: who is the agent acting on behalf of, and what is the audit trail? Futurum's Fernando Montenegro describes the underlying problem in the 2026 Key Issues and Predictions report: "we built access control around principals that have accountability, and agents have none." The practical requirements, as Pothukuchi laid them out on Six Five, are identities distinct from the people agents act for, access scoped to the task rather than inherited from a user's accumulated privileges, and an end-to-end audit trail. The same conversation cites a bank that took seven months to clear compliance for a single agent. Per-decision records should capture the input sources, model version, reasoning, and any human approval.
The regulatory timeline makes this concrete. The EU's Digital Omnibus on AI, published in the Official Journal on 24 July 2026, set fixed dates for the delayed high-risk rules. According to the European Commission's AI Act implementation timeline, rules for high-risk systems listed in Annex III apply from 2 December 2027, and rules for high-risk AI embedded in Annex I regulated products apply from 2 August 2028. The Act's high-risk requirements include automatic logging, with logs kept for at least six months unless other law provides otherwise, along with provisions for human oversight. An agent operating in an Annex III high-risk use case inside the EU will need the audit trail described above in place before December 2027, which means designing it into the data layer during the coming months, not retrofitting it. Futurum expects tying agent identity entitlements to real-time data context to become a prerequisite for passing audits under frameworks such as the EU AI Act and ISO/IEC 42001.
A 12-month sequence for getting agent-ready
Across Six Five's 2026 conversations and the Futurum and Moor Insights & Strategy research, a consistent order emerges. It matters because each step makes the next one cheaper.
- Pick the decisions and redesign the process, not just the use case. List the specific decisions an agent will make and the data each decision depends on. Anything on the list that only needs a routine workflow is automation, not an agent, and should be built as such. Futurum recommends treating a documented process-redesign methodology as a gating requirement before a pilot begins.
- Connect and classify the data behind those decisions. Moor Insights & Strategy recommends completing a data topology audit before selecting agent infrastructure. Close the connectivity gap for the systems in scope only. Attach sensitivity, ownership, and freshness metadata at ingestion so the context layer has something to work with.
- Publish data products as MCP servers. Wrap each governed dataset or tool in an MCP server with scoped credentials and a clear description of what it does. This is the point at which any compliant agent framework can consume your data under your rules.
- Stand up the semantic and memory layers. Agree business definitions once; give agents a memory store with explicit retention policies rather than letting each prompt carry its own history.
- Give every agent an identity and a log. Per-agent credentials, per-decision records, and a human approval gate for any action with financial, legal, or safety impact. Futurum describes the emerging baseline as "read informs, write requires approval".
- Add A2A only when you have more than one agent that needs it. Multi-agent coordination adds cost and failure modes; introduce it when a single agent provably cannot own the task.
- Instrument cost per completed task. Track inference calls, retrieval volume, and tokens per successful outcome from day one, alongside the share of pilots that reach production, which Futurum argues buyers should track as a standing metric. With 46.9% of enterprises already over their AI budgets, measuring early is the only way to see escalation before it stalls the project.
The Six Five POV
The Six Five read is that data readiness is a product challenge that cannot be solved with a one-off migration. Each dataset an agent depends on should be treated as a product with an owner, a published contract (schema, freshness, permissions), and a consumption interface agents can use directly. Open protocols (MCP for context and tools, A2A for agent coordination) are preferable to proprietary connectors so that the governance applied at the data layer survives a change of agent vendor; Futurum's 2026 predictions underscored interoperability through open standards like MCP and A2A, rather than depth in any single stack, to decide which vendors own the agent control plane. And the audit trail should be designed first, because it is far cheaper to log every decision from the start than to reconstruct one for a regulator or an incident review.
The organizations that move past Futurum's 47% adoption plateau in 2027 will not be the ones with the most agents. They will be the ones whose agents can be trusted with data because the data, and the orchestration around it, was built to be trusted. The next phase of agentic AI won't be decided by the models. It will be decided by the data layer underneath them.
Get insider access to Six Five Media's analyst coverage, major tech events, and executive interviews at sixfivemedia.com.
Frequently asked questions
What is the difference between agentic AI data and training data?
Training data shapes a model's weights before deployment. Agentic AI data is the live operational context and semantic layer that an agent reads and writes while performing a task: records, documents, events, tool outputs, memory of previous steps, and the metadata that tells the agent whether that information is fresh, permitted, and trustworthy. Most enterprise agents use foundation models they didn't train, so the operational data layer is where the organization's work happens.
Do I need MCP and A2A, or just one of them?
They solve different problems. MCP standardizes how an agent connects to data sources and tools. A2A standardizes how agents discover and collaborate with one another. A single agent with several tools needs MCP only. A system where a planning agent hands work to specialist agents built on different frameworks needs both. Neither handles authorization on its own, so plan for a gateway and policy layer above them, as Futurum's analysis argues.
Why do so many agentic AI projects stall before production?
Futurum's data points to infrastructure rather than models. Enterprise agentic AI adoption is leveling off at 47%, with data integration the most commonly cited primary bottleneck; 46.9% of enterprises are running AI spend over budget; and 93% of organizations struggle to establish production governance. Futurum's process-redesign research adds that agents also fail when they are layered on top of an unchanged operating model.
What does the EU AI Act require from AI agents?
The Act applies by risk category rather than by technology, so an agent is regulated according to what it does. Under the European Commission's current timeline, as amended by the Digital Omnibus on AI, Annex III high-risk obligations begin on 2 December 2027, and Annex I high-risk obligations on 2 August 2028. High-risk systems must support automatic logging, log retention of at least six months, and human oversight, all of which depend on the audit and identity design of the agent's data layer.
Where should a data team start if the budget only covers one thing in 2027?
The context and metadata layer is the prerequisite for safe retrieval, for meaningful audit logs, and for cost control. Futurum's research shows the market moving the same way: 44.5% of technology leaders plan to increase semantic layer investment over the next 24 months, and data labeling and enrichment is the hands-on work of telling systems what data means. That challenge is still growing. Connecting more data to an agent that cannot judge its freshness or sensitivity increases risk faster than value.
AUTHOR
SHARE


Related Content
Further Reading
Get insider access to Six Five Media's analyst coverage, major tech events, and executive interviews
